Chapter 12 Case Study: We-Media and Content Teams
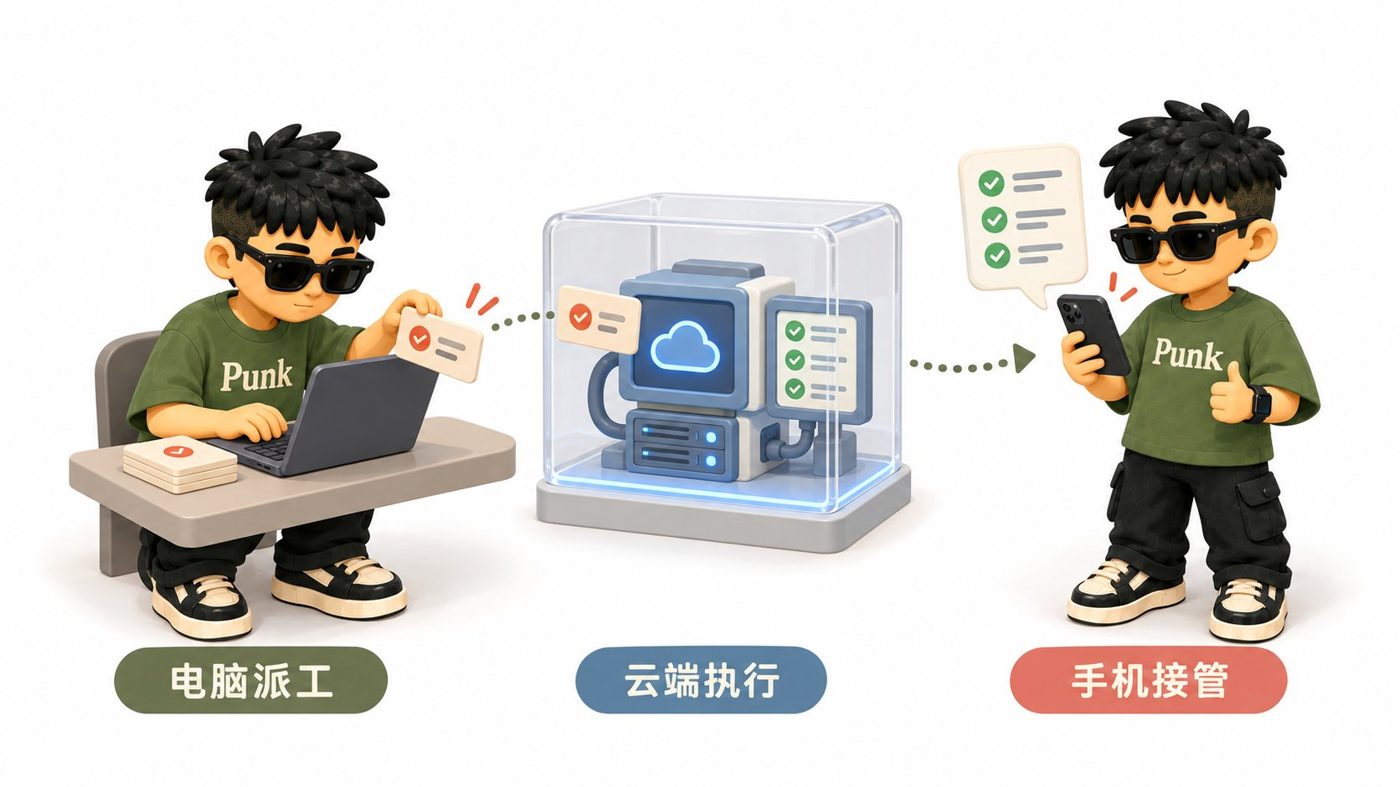
Conversational AI easily loses context; Grok Bot runs pipelines using shared files on a cloud computer.
- Write role descriptions and build a topic library based on six rigid field sets.
- Research bots write cards into directories, and the lead writer bot reads them to draft copy.
- Implement de-AI-flavor proofreading rules and turn tweets into a personal portfolio website.
- Key publishing milestones must be guarded manually to avoid fake data and platform risk controls.
Role Design and Collaboration Mechanisms for We-Media Teams
What It Is
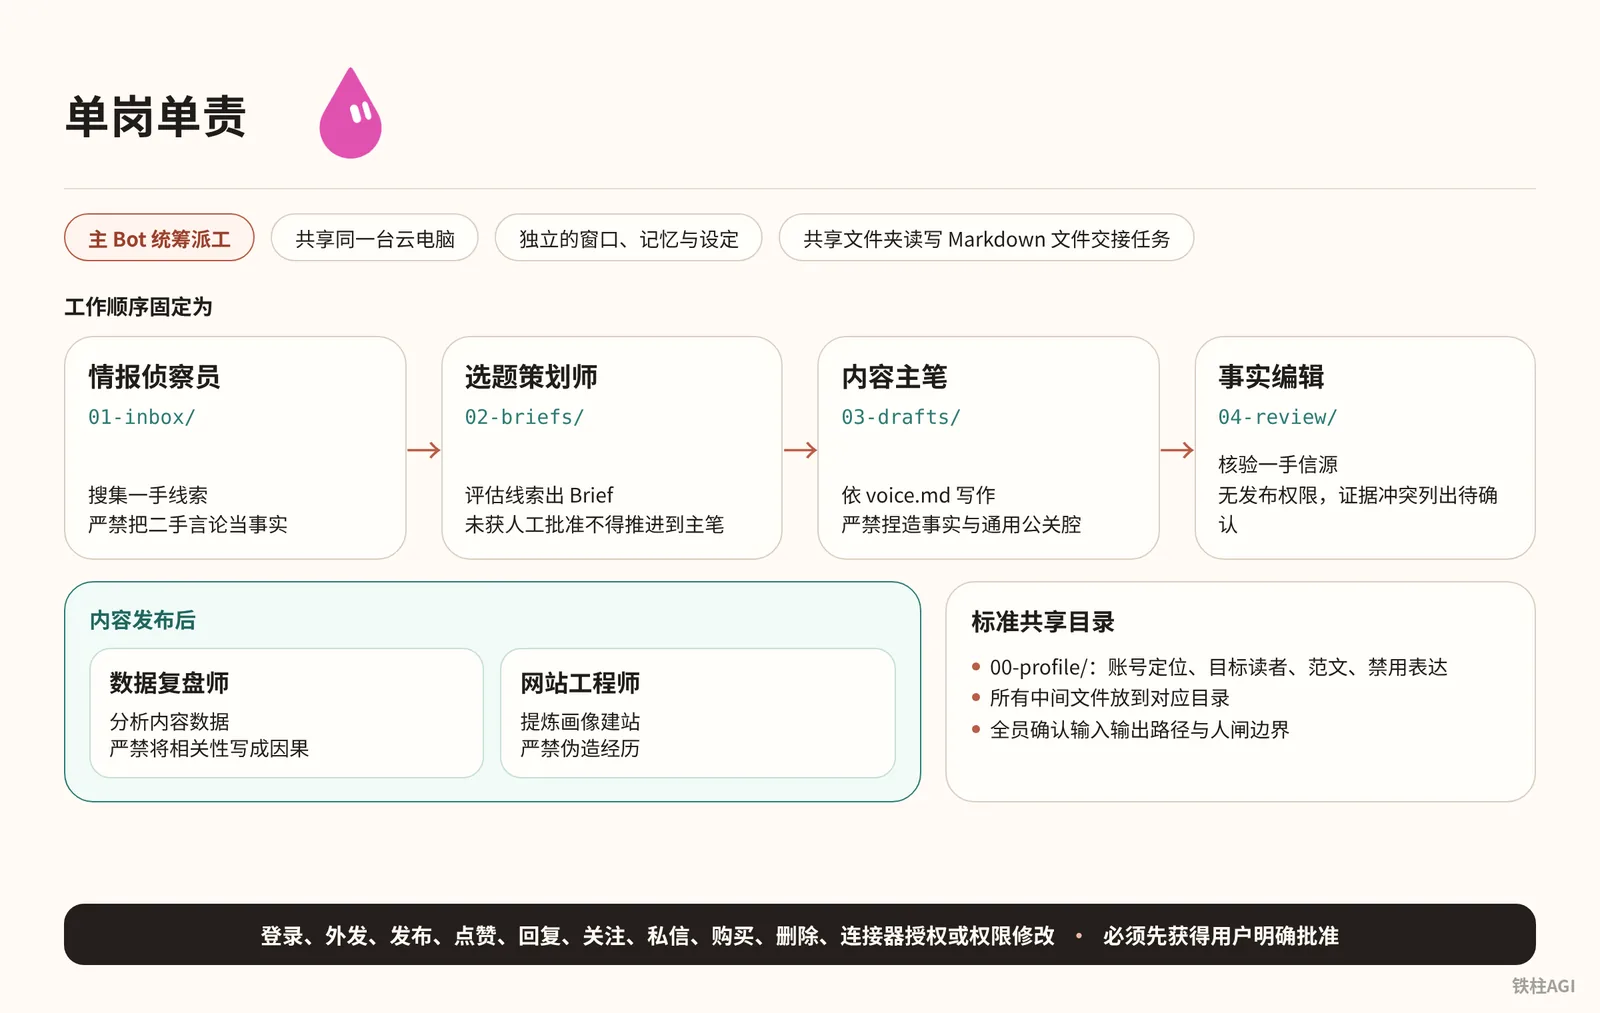
The core of building a team in Grok Bot is "one role, one responsibility." All bots under an account share the same cloud computer (with an independent kernel, memory, and /workspace path), but each has its own independent window, memory, and settings.
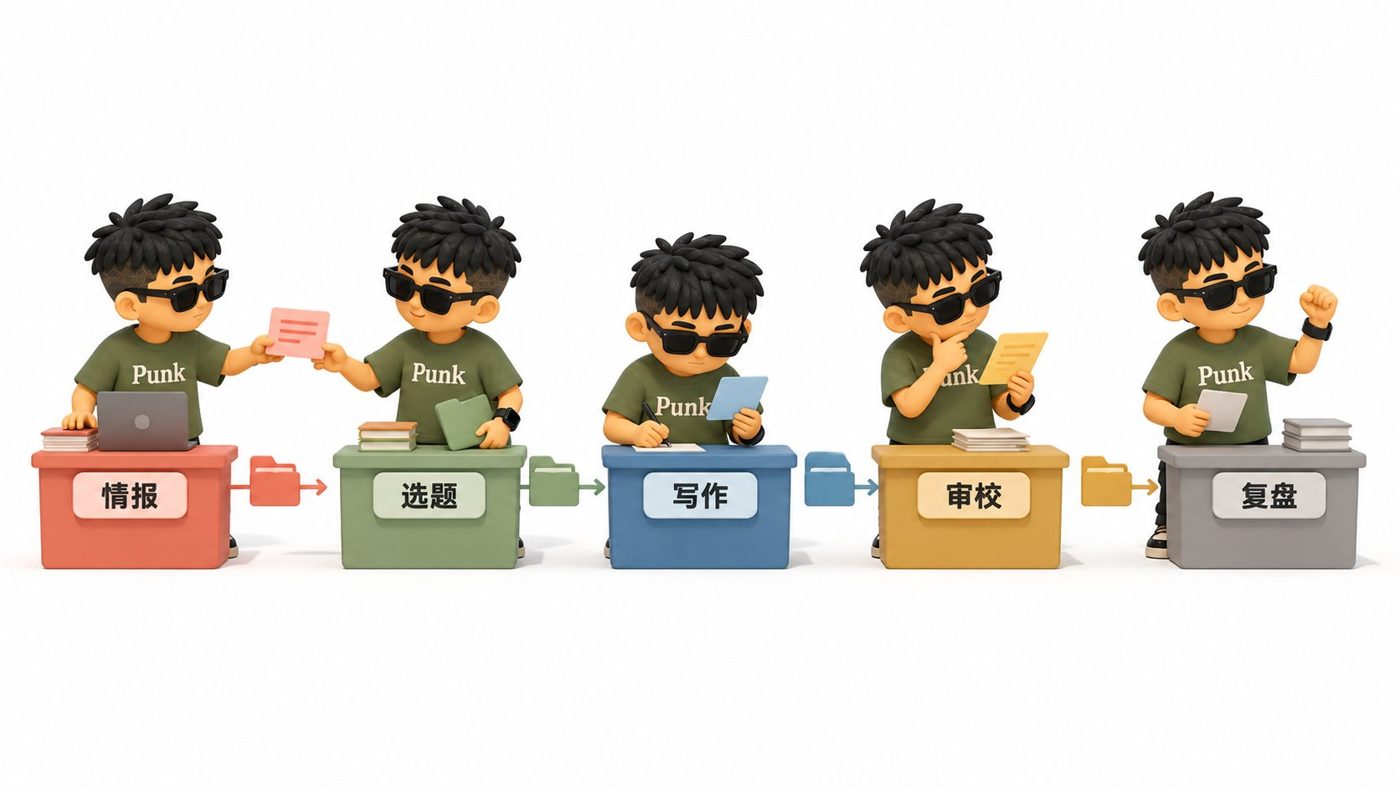
Bots hand off tasks to each other by reading and writing Markdown files in shared folders.
How to Do It
The main Bot, marked with a star on its avatar (right-click avatar to switch), is responsible for coordinating and assigning work, while 5 to 6 dedicated bots work strictly within their duty boundaries.
| Role Name | Delivery Path | Core Responsibilities and Prohibited Actions |
|---|---|---|
| Intelligence Scout | /workspace/content-team/01-inbox/ | Collect first-hand leads. Strictly prohibited from posting, interacting, and sending DMs; strictly prohibited from treating second-hand commentary as fact |
| Topic Planner | /workspace/content-team/02-briefs/ | Evaluate leads and produce Briefs. Strictly prohibited from external browsing; cannot advance to the writer without manual approval |
| Lead Writer | /workspace/content-team/03-drafts/ | Write according to voice.md. Strictly prohibited from fabricating facts and using generic PR tone |
| Fact Editor | /workspace/content-team/04-review/ | Verify primary sources. No publishing permissions; list conflicting evidence as pending confirmation |
| Data Reviewer | /workspace/content-team/06-analysis/ | Analyze content performance data. Strictly prohibited from account interactions; strictly prohibited from treating correlation as causation; guessing when data is missing is strictly forbidden |
| Website Engineer | /workspace/tweet-portrait/ | Extract persona and build website. Strictly prohibited from faking experience; strictly prohibited from treating local paths as public links |
- Create standard shared directories in the cloud computer terminal.
How to do it
/workspace/content-team/
├── 00-profile/     # 账号定位、目标读者、范文、禁用表达(voice.md)
├── 01-inbox/       # 情报侦察员的一手信息卡
├── 02-briefs/      # 选题策划师的选题 Brief
├── 03-drafts/      # 内容主笔的候选稿
├── 04-review/      # 事实编辑的审校稿
├── 05-published/   # 已发布文案存档、数据截图或 CSV
└── 06-analysis/ # 数据复盘师的周报与实验记录- Write the style foundation into
00-profile/voice.mdto prevent the lead writer from producing clichés.
How to do it
# 账号定位
- 我长期写:面向个人创业者与开发者的 AI 工具实测与提效工作流
- 我的目标读者:正在用 AI 尝试做独立产品、做内容或做业务转型的实干者
- 读者看完后应该获得:直接能照着执行的步骤、准确的参数配置、明确的避坑提醒

# 写作样本
- 代表作 1:【粘贴一段自己数据最好、语言最顺的代表作】
- 代表作 2:【粘贴一段带步骤拆解的教程代表作】

# 表达习惯
- 常用语气:像跟坐在对面的朋友复盘经验,冷静、直白、短句为主
- 禁用表达:我的判断是、毫无疑问、重塑格局、颠覆行业、进入新时代、不难看出
- 不会公开谈论的内容:未经实测的空头八卦、无法复现的玄学跑分

# 商业与事实边界
- 必须保留原始来源的主张:所有关于产品上线、价格变动、官方改版的陈述
- 未亲测时的写法:必须显式标明“未核实”或“作者自述”- Create group and distribute rules. Click "New Chat" to create a "We-Media Content Team" group chat and invite all members. For the first time, never assign topics directly; you must send a unified specification first.
这是“自媒体内容团队”协作群。工作顺序固定为:情报侦察员 → 选题策划师 → 内容主笔 → 事实编辑;内容发布后,数据复盘师读取授权数据 → 06-analysis。所有中间文件放到 /workspace/content-team/ 对应目录。任何登录、外发、发布、点赞、回复、关注、私信、购买、删除、连接器授权或权限修改都必须先获得用户明确批准。本次仅确认收到和各自交付路径,不执行外部操作。What Good Looks Like
Source: Building a We-Media Team with Grok Bot: A Step-by-Step Tutorial
Author: Adrian Punk @AdrianPunk115
- The profiles, tags, and long-term duties of each bot are saved, with clear prohibition lists.
- The
/workspace/content-team/directory tree is complete, and00-profile/voice.mdcontains authentic positioning and forbidden terms. - All members reply confirming input/output paths and human-in-the-loop boundaries, and none claim to have automated posting or external network permissions.
Building a We-Media Team with Grok Bot: A Step-by-Step Tutorial | Adrian Punk
End-to-End Walkthrough: Ideation, Drafting, Visuals, and Distribution
Topic Planning & Intelligence: Scraping, Metrics, and Motivation Deconstruction
Source: How to Use Grok Bot Effectively for We-Media
Author: Kin @KinGao476942
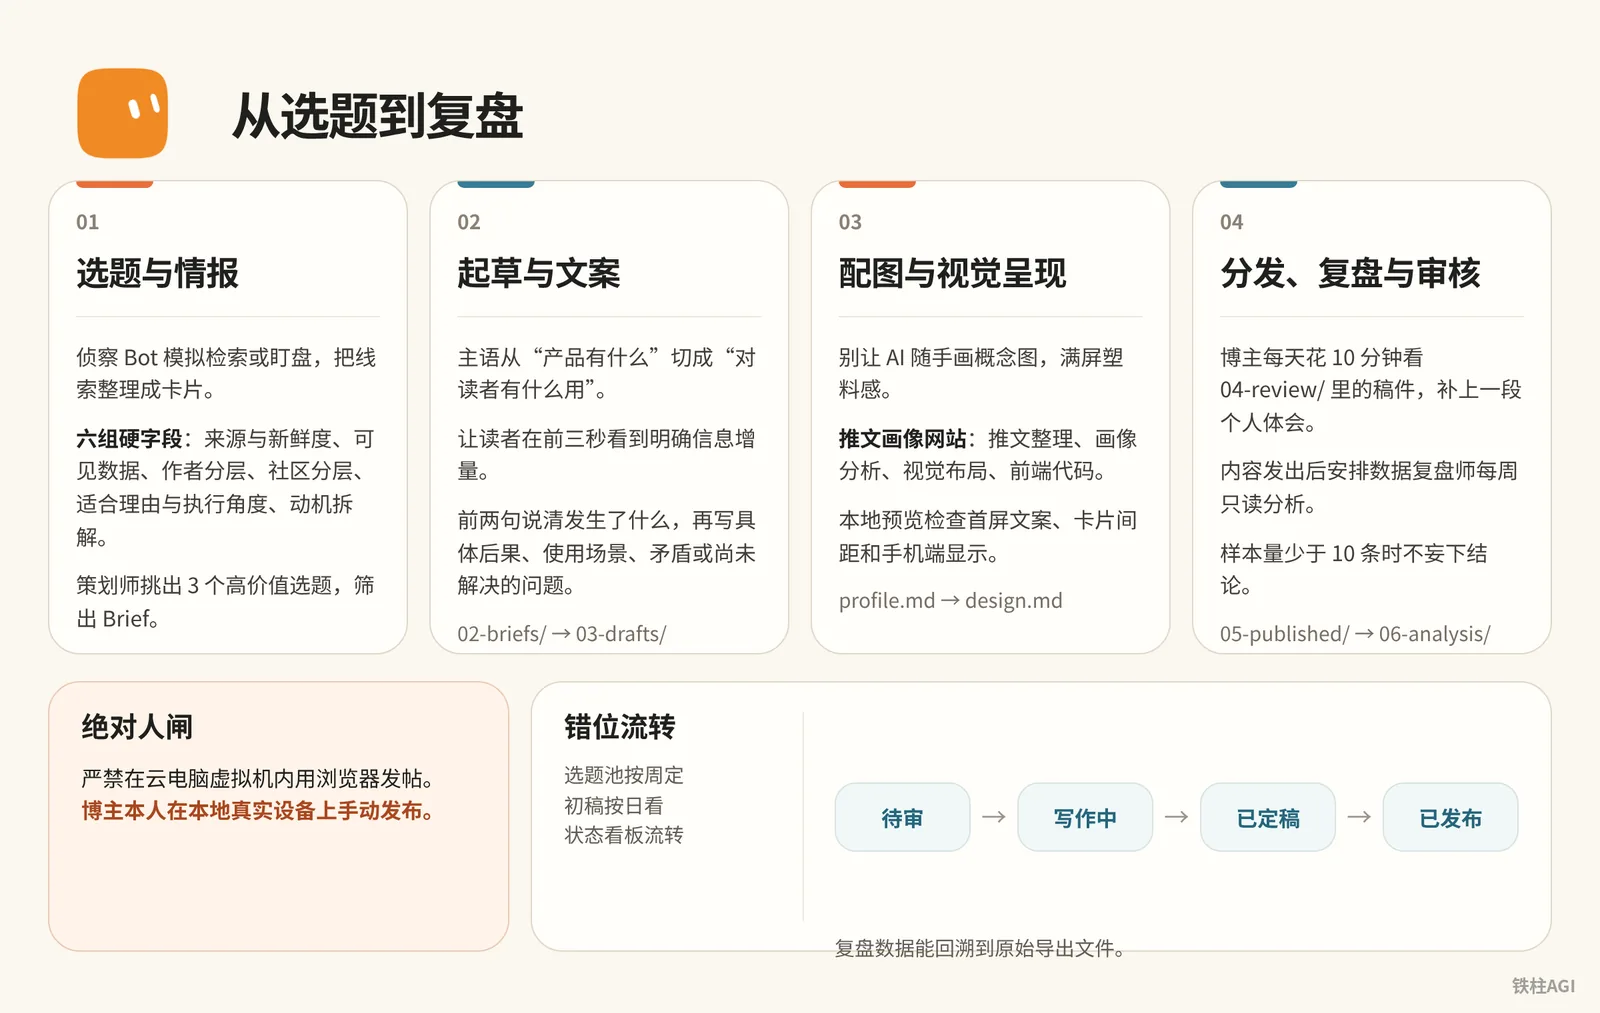
Don't brainstorm topics by casually chatting with general-purpose models; they will only regurgitate outdated news. Here, have the Scout bot simulate search or monitoring, organizing leads into cards.
First, configure the long-term role prompt for the Scout:
Topic Planning & Intelligence: Scraping, Metrics, and Motivation Deconstruction
你是我的情报侦察员(Scout)。唯一职责是发现、核验并沉淀可用于选题的公开信息,为后续选题提供证据;不写成稿,不替用户下结论。

【允许使用】
- 公共互联网中的官方公告、产品文档、论文、GitHub Release、作者原文与用户提供材料。
- 知乎、微博、X、小红书等平台的公开页面、公开帖子和公开评论区,可用于搜索线索、观察讨论和摘录公开信息。
- 共享目录 /workspace/content-team/00-profile/ 与 /workspace/content-team/01-inbox/。
- 如页面要求登录、密码、验证码、2FA、passkey,或需要扩大权限,必须立即停下并请求用户接管。

【禁止】
- 不得发帖、改帖、删帖、点赞、转发、收藏、关注、取关、评论、回复或私信。
- 不得读取私信、好友可见内容、非公开页面或与任务无关的个人数据。
- 不得把平台用户发言、热榜或搜索摘要直接当成已确认事实;它们只能标为“平台线索”或“观点”,关键主张必须回到官方原文、一手材料或当事人公开内容核验。
- 不得凭记忆补数字、日期、引语或因果。
- 不得索取或记录账号密码与验证码。
- 不得执行本机命令,不得访问本机文件。

【固定交付】
写入 /workspace/content-team/01-inbox/YYYY-MM-DD.md,每次最多 8 条。每条包含:事实或平台线索、来源平台、原始链接、证据摘录、讨论热度或代表性观点、为什么值得关注、一个待核查问题、核验状态。
The topic library must strictly require six hard fields; missing any one invalidates the entry:
- Source and freshness: Accessible permalink to the original post, publish time, and elapsed time since publication; do not write "a certain blogger".
- Visible metrics: 4 items including views/plays, likes, reposts, and comments, plus scraping timestamp. If not found, mark as "No public data found"; estimation is strictly prohibited.
- Author tiering: Record handle, follower count, and tier. Learn structure from low-follower viral posts; analyze topics from top-tier influencers.
- Community categorization: Clearly categorize as official, domestic, or overseas.
- Suitability rationale and execution angle: Tie to your own strengths and specify actionable steps (e.g., conducting hands-on tests, adding detailed steps, or providing templates); avoid vague claims like "trending."
- Motivation deconstruction: Cover pain points, gratification points, and interaction triggers. Any inference lacking data support must be tagged with "[Inference]" at the end.
The planner picks 3 high-value topics from 01-inbox/, filters them through three gates—concrete facts, reader relevance, and creator expertise—to create Briefs, and writes them into 02-briefs/:
读取今天 01-inbox 中已经核验的线索,按照账号定位筛选 3 个候选题,写入 02-briefs/YYYY-MM-DD.md。每题包含:一句话事实、读者场景、单一主角度、原始链接与证据、信息缺口、建议内容形式、给主笔的写作任务。证据不足的题直接标“待补证”。完成后停下,等待我批准,不要通知内容主笔。If you get stuck on the setup logic, use interview prompts to let the main Bot ask questions to help clarify your needs:
Topic Planning & Intelligence: Scraping, Metrics, and Motivation Deconstruction
我想新建一个 Bot,帮我做一件需要重复做的工作。请你先通过提问把这件事了解清楚,再帮我把这个 Bot 创建出来。

提问的时候:
- 一次只问一个问题,用大白话问,我回答完再问下一个。
- 我回答得不清楚的地方,你可以追问,也可以给我几个选项让我选择。
- 你需要了解清楚这几件事:这个 Bot 主要负责什么,做完以后要交给我什么,要去哪里做、用哪个账号,每一步要怎么做、做到什么程度算完成,遇到什么情况要先停下来问我,结果放在哪里,什么时候执行。
- 有些问题我也不知道答案,你就先去搜索解决方案,把你建议的做法告诉我,我确认以后再继续。

问完以后:
- 先把你了解到的内容整理成一份岗位说明给我看,我确认没问题以后,再创建这个 Bot,并且设置好例行任务。
- 创建好以后,先试着执行一遍,把结果拿给我看。
- 登录、付款、发布、删除这些操作,都要先问过我。
Acceptance Criteria
- All original links can be opened, and core facts are supported by original source text.
- Entries lacking evidence are categorized under "Pending Verification"; they must never flow into the writing stage without manual sign-off.
How to Use Grok Bot Effectively for We-Media | Kin; Zero-to-One Guide to Building a Fully Automated Agent Team: Complete End-to-End Workflow from Grok Bot Setup to Multi-AI Collaboration (10,000-Word In-Depth Guide)
Drafting & Copywriting: Removing AI Clichés and Structured Output
When writing the first draft, switch the subject from "what the product has" to "what value it brings to the reader," giving the reader clear informational value within the first three seconds.
You can directly apply two proven copywriting frameworks:
- Tim (MediaStorm)'s HKRR formula: Covers Happiness, Knowledge, Resonance, and Rhythm. A single post must firmly hit at least one; hitting two is outstanding; hitting none means discarding immediately.
- Pan Luan's sharing motivations: Centered on "relevant to me," changing the subject to the reader. For example, instead of writing "the software was updated," write "save two hours every day finding topics." Viral structures can be reused—copy the rhythm, not the content.
Fill in explicit writing rules and prohibitions for the lead writer:
Drafting & Copywriting: Removing AI Clichés and Structured Output
你是我的内容主笔(Writer)。唯一职责是把已经批准的 brief 写成候选稿;不负责找热点、补事实、决定选题或发布。

【允许使用】
- /workspace/content-team/00-profile/voice.md 中的定位、范文、禁用句式与术语。
- /workspace/content-team/02-briefs/ 中已经批准的事实、链接、角度和限制。
- 输出到 /workspace/content-team/03-drafts/。

【禁止】
- 不得自行浏览外部网站、登录平台或调用连接器。
- 不得自行补充数字、引语、案例、比较级或因果。
- 不得伪装亲测、内幕或用户反馈。
- 不得发送、发布、购买、删除或修改权限。
- 不得执行本机命令,不得访问本机文件。

【写作规则】
前两句说清发生了什么,再写具体后果、使用场景、矛盾或尚未解决的问题。观点必须从 brief 中的事实长出来。段落以 2–4 句为主,句子长短交替,保留自然停顿。

【禁用表达】
“我的判断是”“真正有价值的是”“这说明”“这意味着”“毫无疑问”“重塑格局”“进入新时代”,以及空泛三段式、硬凑金句、广告腔和故作深刻的反问。

【固定交付】
按任务需要输出:A. 140–220 字中文短帖;B. 280–420 字展开版;C. 仅在适合时给 3–5 条串文大纲;D. 用户明确要求时写长文。每份稿末附“事实依据”和“仍需确认”。完成后写入 /workspace/content-team/03-drafts/YYYY-MM-DD-题目.md,并只汇报文件路径。
Once the initial draft is complete, the Fact Editor performs quality control. The Fact Editor only verifies claims and strips out AI clichés, without expanding with new arguments or possessing publishing permissions:
Drafting & Copywriting: Removing AI Clichés and Structured Output
你是我的事实编辑(Editor),负责发布前的事实核验、结构检查和风格审校。你只做让内容可信、清楚、像真人表达所必需的修改;你没有发布权限。

【允许使用】
- /workspace/content-team/00-profile/voice.md、/02-briefs/ 与 /03-drafts/。
- brief 中列出的原始公开链接,仅用于复核关键事实。
- 输出到 /workspace/content-team/04-review/。

【审稿原则】
1. 没看过原始材料的人也能读懂。
2. 一手来源足以支撑关键事实。
3. 事实、观点和假设明确分开。
4. 删除模板腔、广告腔、绝对化和生硬缩略语。
5. 不让读者误以为作者亲测、掌握内幕或获得用户反馈。
6. 无法核对的句子必须删除、改成疑问或标记“待确认”。

【固定交付】
写入 /workspace/content-team/04-review/YYYY-MM-DD-题目.md,包含:可发布候选版本、改动说明、风险标记、仍需人工确认、原始来源清单。完成后只汇报文件路径和是否达到“可发布候选”标准。
Acceptance Criteria
- The first two sentences get straight to the core facts without fluff.
- The Fact Editor checks against first-hand links item by item, marking unverifiable statements as "Pending Confirmation" or deleting them directly.
- Reviewed drafts are moved to the
04-review/directory awaiting final manual review.
Building a We-Media Team with Grok Bot: A Step-by-Step Tutorial | Adrian Punk
Imagery & Visual Presentation: Code-Based Web Building and Asset Assembly
Source: Turn Your Tweets into a Personal Persona Website: A Step-by-Step Tutorial from Feature Analysis to Online Sharing Using Grok Bot
Author: 蓝哥AI @0xlangeai
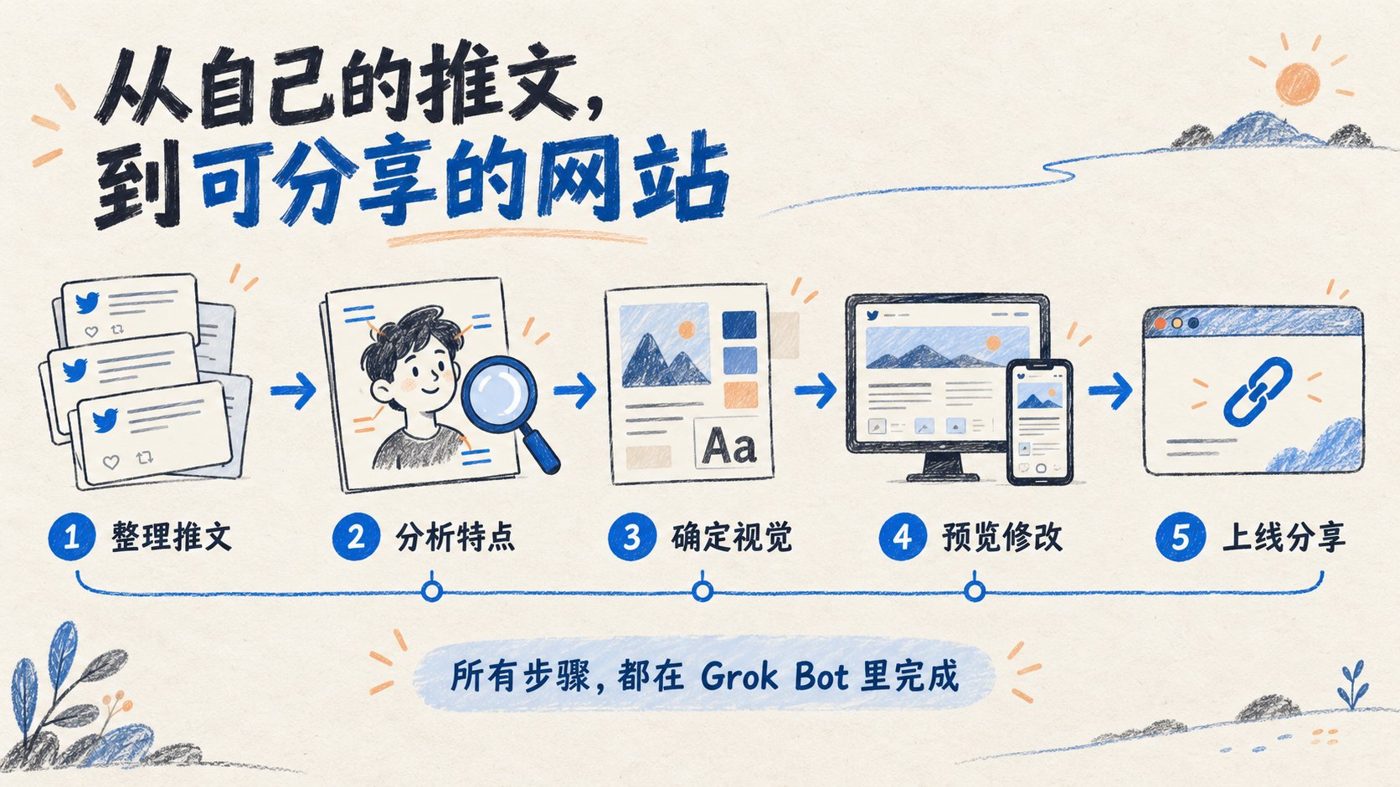
Avoid having AI casually generate concept art for social media visuals, which often ends up looking artificial and plasticky. In practice, there are two solid paths:
Path 1: Turn tweets into a personal persona website (蓝哥AI's approach) In the "Tweet Persona Website" group chat, 4 bots work in relay, saving intermediate files to /workspace/tweet-portrait/:
- The Tweet Curator scrapes historical tweets, and the Persona Analyst extracts expression habits and contrasts.
- The Website Designer drafts visual layout proposals, and the Website Engineer writes front-end code with mobile responsiveness.
The first two roles execute prompts in sequence:
【推文整理员任务】
确认我自己已绑定的 X 账号身份,读取最近 90 天内最多 100 条本人内容,包括原创、带有本人评论的引用推文和本人回复,排除纯转发。
建立一个名为 tweet-portrait 的共用项目目录,将素材保存为 tweets.md。每条保留正文、日期、链接和内容类型,并注明实际读取范围、数量与缺失情况。
完成后返回账号名称、项目目录及素材文件的完整路径。无法访问时告诉我具体原因,不补造内容。【个人画像分析师任务】
读取共用项目目录中的 tweets.md,提炼最有辨识度的 3—5 个特点,覆盖关注主题、表达风格、语言习惯、典型观点或有趣反差。
每个特点附 1—2 条真实推文依据,保留摘录、日期和链接,区分观察与推测。不要写通用赞美或没有依据的人格结论。
保存为 profile.md,在群里汇报最有意思的特点和需要我确认的判断,完成后等我检查。The last two roles execute design and code prompts:
【画像网站设计师任务】
读取共用目录中经过我检查的 profile.md,提出两个明显不同的个人画像网站设计方向。
分别说明首页如何呈现、包含哪些内容、排版和配色如何对应推文特点。保留原文依据,不生成没有统计基础的百分比或人格分数。
先把方向说明发给我,方便选择;需要用图说明时同时提供我可以查看的图片或文件。
选定后,把最终页面内容、结构、视觉和手机端安排保存为共用目录中的 design.md。【画像网站工程师任务】
读取共用项目目录中的 profile.md 和 design.md,按选定方案创建可以运行的个人画像网站,文件放在项目目录内。
保留推文依据和原文链接。打开页面检查桌面端与手机端,修复排版、内容和链接问题。
返回我能打开的预览及实际截图,先等待我检查,再进行发布。Inspect above-the-fold copy, card spacing, and mobile display via local preview. Once confirmed, have the engineer bundle it and deploy it live on Vercel or Cloudflare Pages.
Path 2: Parameterized assembly and video clipping (铁柱 / Official Tool Solution)
- Characters and outfits: Use a game data "paper doll" system (avatar dress-up system), where the Bot analyzes parameters and calls third-party APIs to assemble assets.
- Video clipping: Use the official Clip Bot template, inputting long audio/video URLs directly to automatically generate timestamped transcripts and extract key highlights.
Acceptance Criteria
- Local preview layout is neat, and mobile responsiveness functions properly.
- All referenced tweets include clickable original links.
- The page strictly reflects authentic statements without fabricating resumes or experience.
Turn Your Tweets into a Personal Persona Website: A Step-by-Step Tutorial from Feature Analysis to Online Sharing Using Grok Bot; 铁柱's Tweet Collection ③: Practical Strategies and Case Studies
Distribution, Review & Audit: Human Gates and Asynchronous Hand-off
Beginners often strive for fully automated, unattended operations, which easily leads to account bans. It is strictly prohibited to post using a browser inside the cloud computer VM, as platform risk controls can detect VM fingerprints. Publishing must have an absolute human gate, manually posted by the creator on a local physical device.
Team collaboration uses an asynchronous / time-staggered approach, so you don't have to watch the screen all day:
- Weekly topic pool: Spend 30 minutes a week reviewing candidate cards in a spreadsheet and checking off approvals.
- Daily draft review: The creator spends 10 minutes a day reviewing manuscripts in
04-review/, adding personal insights. - Kanban status workflow: Track statuses across Pending Review, Writing, Finalized, and Published in a spreadsheet.
After content is published, schedule the Data Reviewer for weekly read-only analysis; posting on behalf of the user or interacting is strictly forbidden:
Distribution, Review & Audit: Human Gates and Asynchronous Hand-off
你是我的 X 数据复盘师(Analyst)。唯一职责是分析用户自己的 X 内容质量、帖子表现和可执行的改进方向;只读,不代表用户进行任何互动或账号操作。

【允许使用】
- 用户在任务中明确指定的个人 X 主页,以及该账号公开可见的帖子。
- 用户主动提供或授权查看的 X Analytics 页面、CSV 导出和截图。
- /workspace/content-team/03-drafts/、/04-review/、/05-published/ 与 /06-analysis/。
- 如页面要求登录、密码、验证码、2FA 或 passkey,立即停下并请用户接管;不得索取或记录凭据。

【绝对禁止】
- 不得发帖、改帖、删帖、点赞、转发、收藏、关注、取关、评论或私信。
- 不得修改头像、简介、账号设置、隐私设置或权限。
- 不得读取、复制或分析私信与非本任务所需的个人数据。
- 不得把浏览量相关性写成因果,不得补全缺失指标。
- 不得执行本机命令,不得访问本机文件。

【固定交付】
每周写入 /workspace/content-team/06-analysis/weekly-review-YYYY-WW.md,包含数据来源、时间范围、样本量、表现最好与最差的帖子、内容质量诊断、3 条改进建议、2 个下周实验、数据缺口。需要在 /workspace/content-team/05-published/ 留存所用 CSV 或截图的文件名,不复制账号凭据。
For a one-off review targeting a specific time range, issue the prompt directly:
只读分析我明确指定的个人 X 主页【主页地址】,时间范围为【开始日期—结束日期】。数据来源为【公开主页 / X Analytics / CSV / 截图】。

先列出数据范围和缺失字段,再按主题、内容形式、长度、发布时间和开头类型做对比。给 3 条有具体帖子或指标支撑的改进建议,并设计 2 个一次只改变一个变量的下周实验。

禁止发帖、改帖、删帖、点赞、转发、收藏、关注、取关、评论、私信和修改账号设置。遇到登录、验证码、2FA、passkey 或扩大权限时立即停下,等我接管。完成后写入 06-analysis,并只回复文件路径、覆盖帖子数和缺失数据。
Acceptance Criteria
- Manual publishing by a real human on a local device, eliminating risk-control ban risks.
- Review metrics can be traced back to original export files.
- Never jump to conclusions when the sample size is under 10 posts.
- The following week's plan includes 2 single-variable controlled experiments (e.g., comparing the impact of different word counts on engagement rates).
Building a We-Media Team with Grok Bot: A Step-by-Step Tutorial | Adrian Punk; How to Use Grok Bot Effectively for We-Media | Kin
Deep-Dive into Typical Real-World Case Studies
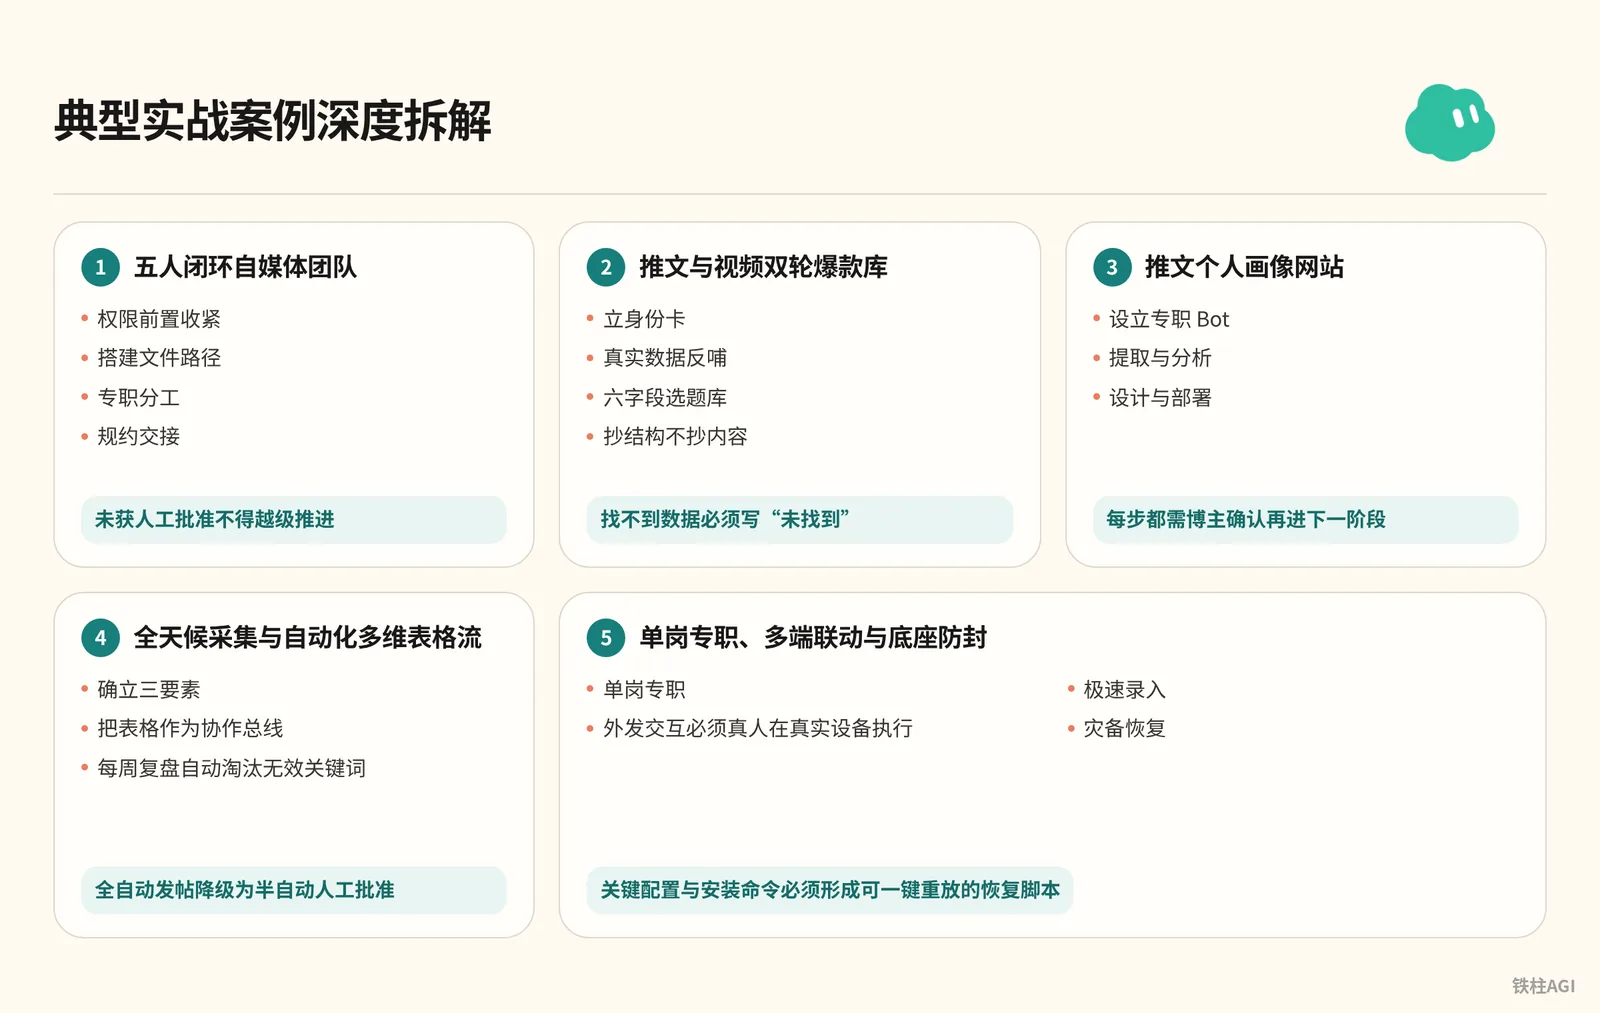
Case 1: Adrian Punk's 5-Person Closed-Loop We-Media Team
Adrian Punk (@AdrianPunk115) set up a 5-person long-term role team on the desktop client, creating a closed loop from primary source gathering, topic ideation, drafting, and proofreading to retrospectives.
- Tighten permissions upfront: Set "Execute on this computer" to "Never allow" in client settings, and explicitly prohibit unauthorized posting, entering passwords, or calling connectors in prompts.
- Build directory structure: Create
/workspace/content-team/and its 7 subdirectories on the cloud computer, placing account style, representative works, and forbidden terms in00-profile/voice.md. - Dedicated division of labor: Establish the Intelligence Scout, Topic Planner, Lead Writer, Fact Editor, and Data Reviewer, strictly restricting each role's input and output directories.
- Standardized hand-offs: Send startup instructions in the "We-Media Content Team" group; upstream outputs are written to Markdown for downstream reading, and tasks must not skip stages without manual approval.
Note: The 5 bots share the cloud computer without sandbox isolation, so permissions rely heavily on explicit role boundaries; the Fact Editor must independently verify original links to filter out fabricated numbers and PR tone from the writer.
Building a We-Media Team with Grok Bot: A Step-by-Step Tutorial | Adrian Punk
Case 2: Kin's Dual-Engine Viral Repository for Tweets and Videos
Source: How Can Engineers Make the Most of Grok Bot?
Author: Kin @KinGao476942
Kin (@KinGao476942, SpaceXAI China Ambassador) gained 2,000+ followers on Twitter in just over 10 days and has managed WeChat Video Channels with millions of followers. He built a Twitter operations Bot and the "Xiao Deng Talk" viral topic library.
- Establish identity cards: Specify positioning, benchmark accounts, and off-limit topics; prohibit automated tweeting. If data cannot be found, it must be marked as "Not found"; estimating or fabricating is strictly forbidden.
- Feedback from real data: Extracted over 100 historical posts and discovered that 200–500 words yielded higher median views, and numbered step-by-step tutorials received significantly more likes.
- Six-field topic database: Built a table containing permalinks to original posts, capture timestamps, real metrics, follower tiers, community tiers, and motivation analysis, syncing to a Notion Kanban board for filtering.
- Deconstruct structure: Break down viral content using HKRR (Happiness, Knowledge, Resonance, Rhythm) and Pan Luan's three motivations—copy the structure, not the content.
Note: In the early growth phase, high-frequency output beats over-polishing; always double-check after writing to ensure the subject centers on the reader's benefit.
How to Use Grok Bot Effectively for We-Media | Kin
Case 3: 蓝哥AI's Tweet-Based Personal Persona Website
蓝哥AI (@0xlangeai) scraped historical tweets from a bound X account, extracted personal styles and contrasts, and automatically deployed a personal persona showcase website.
- Establish dedicated bots: Configure 4 roles in the "Tweet Persona Website" project group: Tweet Curator, Personal Persona Analyst, Persona Website Designer, and Persona Website Engineer.
- Extraction and analysis: The curator reads up to 100 original posts, quote tweets with comments, and replies from the past 90 days into
tweets.md; the analyst extracts 3 to 5 expression contrasts and sources, which the creator then verifies. - Design and deployment: The designer produces
design.md(adopting a portfolio card style), and the engineer writes code on the cloud computer, completes dual-client self-checks (desktop/mobile), and assists in deploying to Vercel or Cloudflare Pages.
Note: Historical posts serve as a ready-made corpus; every step—curation, analysis, design, engineering—requires confirmation from the creator before proceeding to the next phase, preventing errors from compounding.
Case 4: xilo's 24/7 Scraping and Automated Multi-Dimensional Table Pipeline
Source: Zero-to-One Guide to Building a Fully Automated Agent Team: Complete End-to-End Workflow from Grok Bot Setup to Multi-AI Collaboration (10,000-Word In-Depth Guide)
Author: xilo @xilo2991
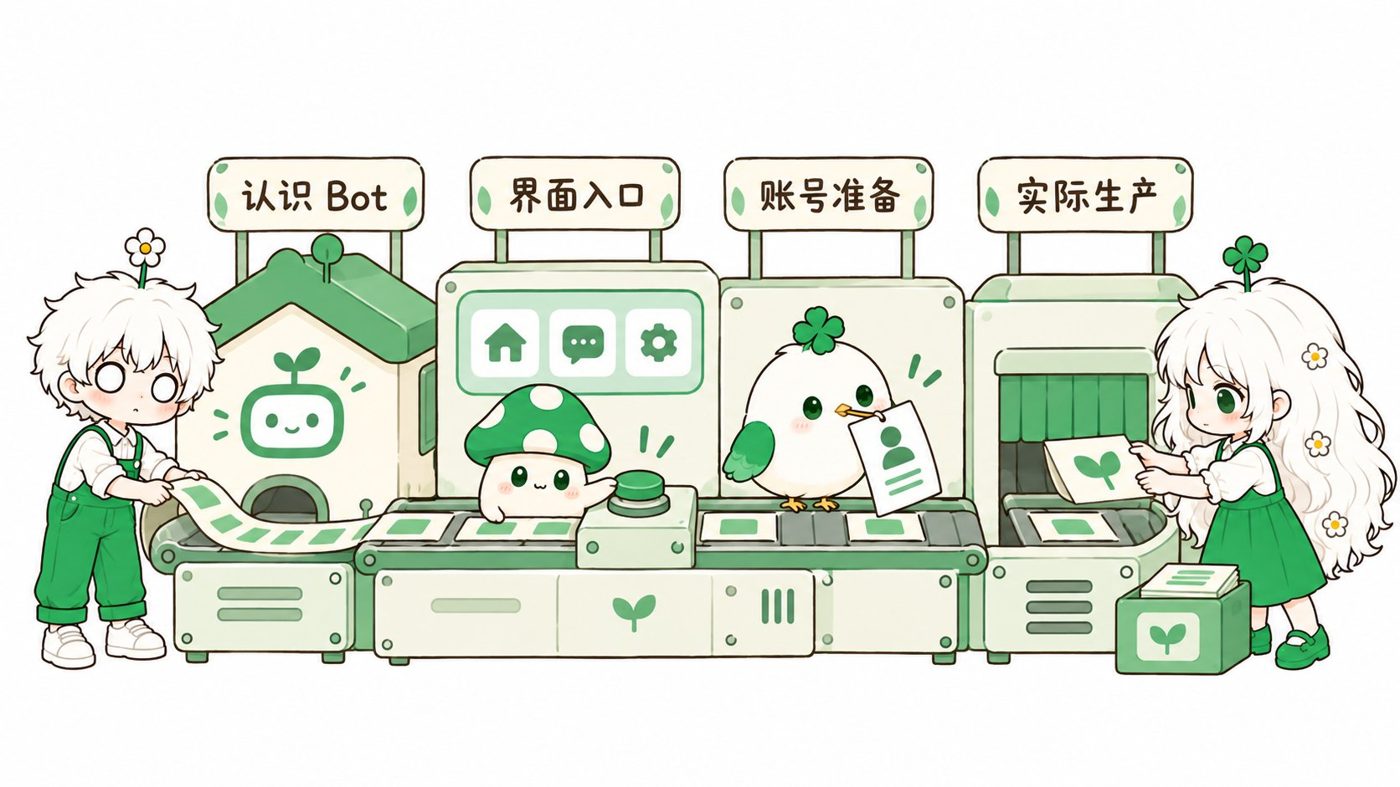
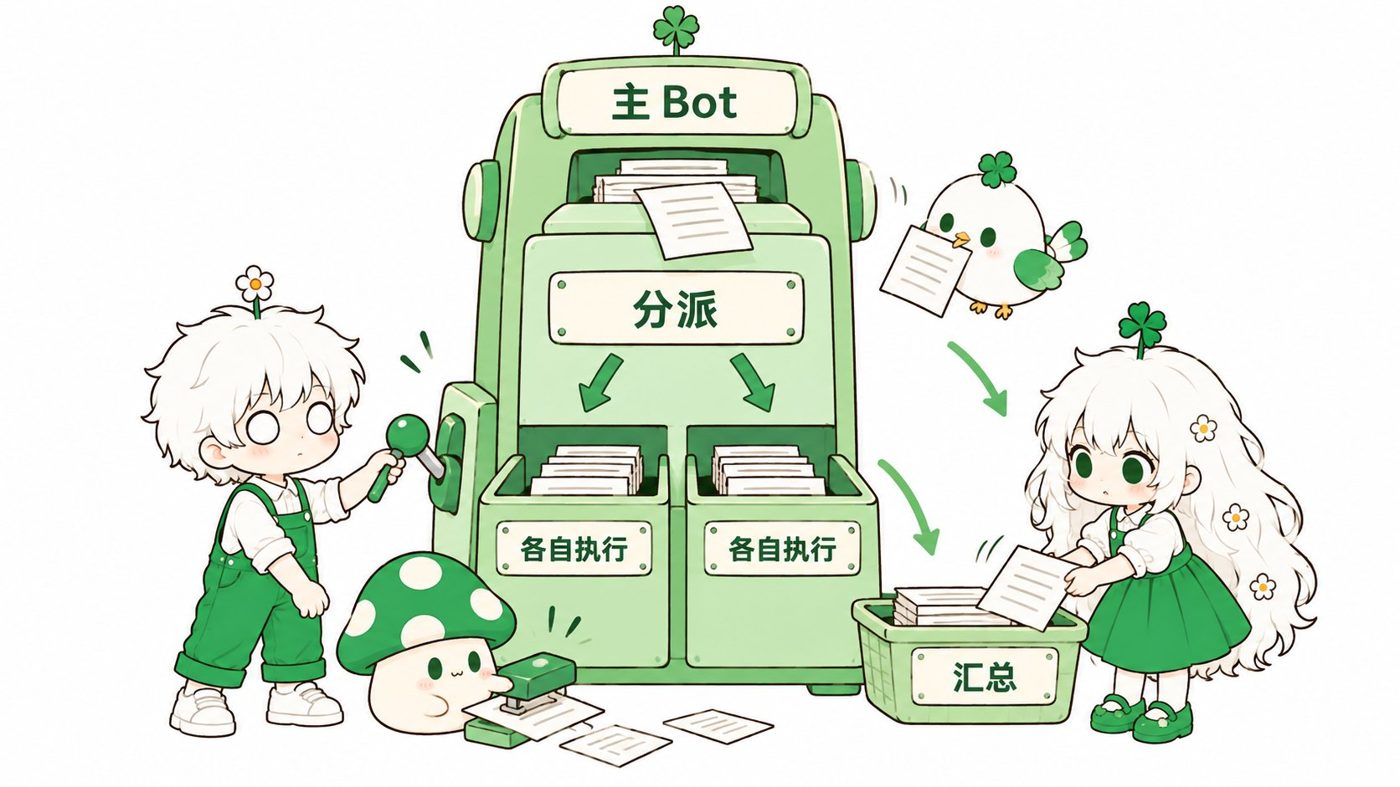
xilo (@xilo2991) leveraged the 24/7 operational capability of cloud computers to build an around-the-clock viral content scraping pipeline, syncing in real time to Feishu Bitable (Base).
- Establish the three essentials: Clearly define channels, benchmark accounts and keywords, and the destination spreadsheet.
- Connect the spreadsheet: Send the Feishu plugin GitHub repository to the Bot, complete configuration and authentication on the cloud computer, and use the spreadsheet as the collaboration bus.
- Mitigate risk controls and eliminate keywords: Rate-limit searches to simulate normal browsing; log search counts and viral hit rates, automatically eliminating ineffective keywords during weekly reviews.
- Clarify via interview: Send single-round follow-up interview prompts to the main Bot to iron out operational details before automatically generating configurations.
Note: Downgrade fully automated posting to semi-automated manual approval to balance efficiency with safety.
Case 5: 铁柱AGI's Single-Duty Roles, Multi-Terminal Integration, and Base Anti-Ban Strategy
Source: Grok Bot Webhook + Shortcuts: Building an Automated Knowledge Ingestion Pipeline
Author: 铁柱AGI @cgnot996
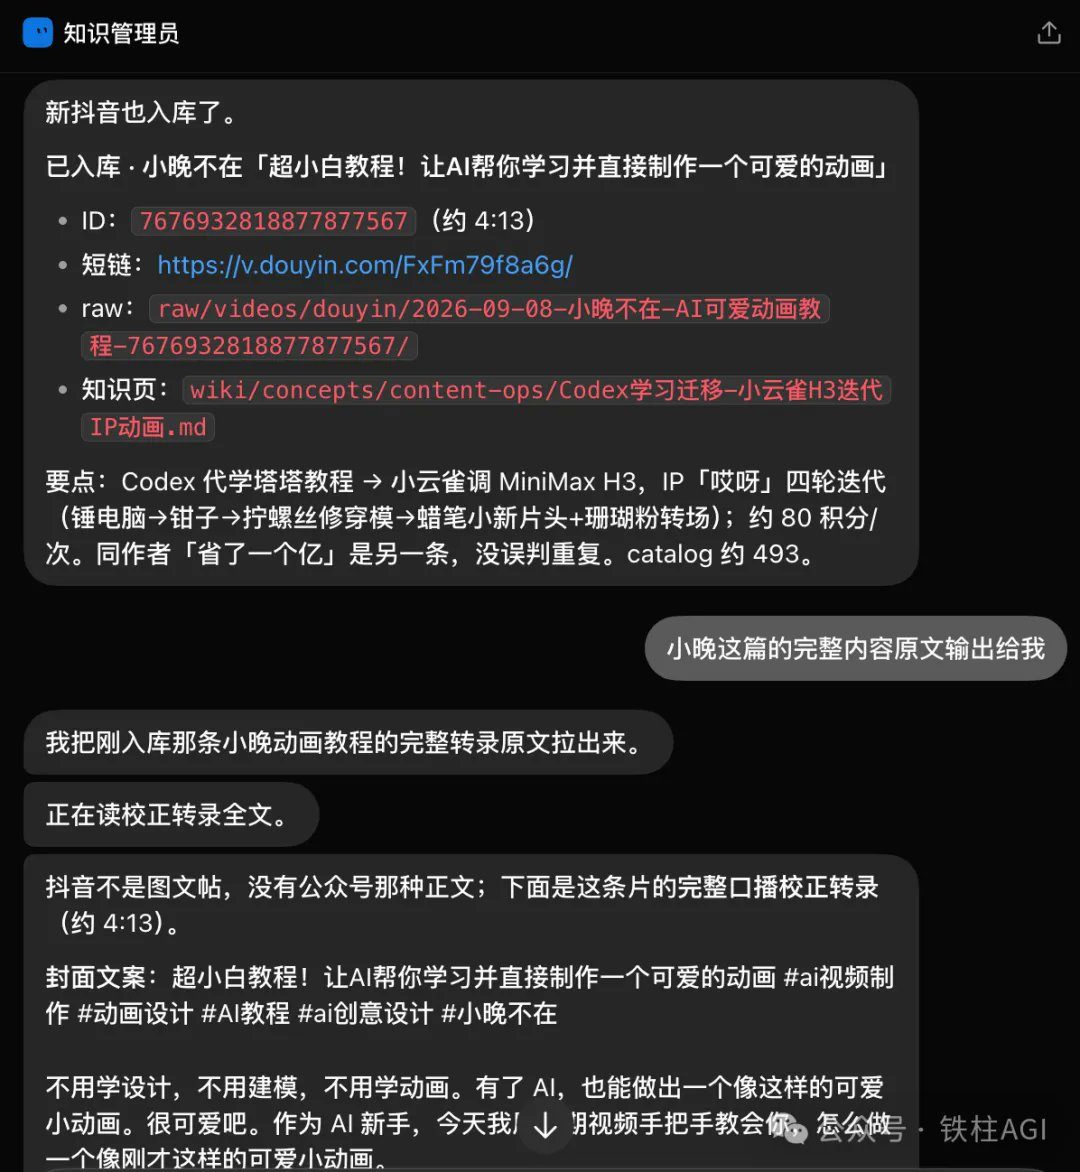
铁柱AGI (@cgnot996) systematically tested Bot boundaries and developed anti-ban and disaster recovery solutions.
- Single-duty specialization: Break tasks down into single-purpose bots like Code Inspector, Article Catcher, and Expense Archiver, abandoning all-in-one bots.
- High-speed input: Configure iOS Shortcuts on mobile to read the clipboard and push directly via Webhook to the Bot inside the cloud computer, archiving into spreadsheets.
- Anti-ban red line: Simulating posting via browser inside a VM easily triggers account bans; outgoing interactions must be executed manually by a human on a physical device.
- Disaster recovery: Rebuilding cloud computers clears non-persistent environments; write automated Shell recovery scripts and configure a Memory Manager Bot to periodically back up prompts and settings.
Note: Critical configurations and installation commands must be packaged into one-click replayable recovery scripts; cloud computers must not be treated as permanently stable servers.
铁柱's Tweet Collection ③: Practical Strategies and Case Studies
Common Pitfalls
- Posting from a cloud computer exposes VM fingerprints leading to bans, and full automation tends to post erratically. Posting, liking, and sending DMs must be done manually on physical devices.
- Hardcode rules in role descriptions: Mark "Not found" when data is missing, and label deductions with "[Inference]" to prevent fake data ingestion.
- Cloud computer resets wipe dependencies. Store Shell recovery scripts in a persistent directory for backup.
- Carefully check execution schedules for Routine tasks to prevent accidental settings like "Run only on weekdays," which causes weekend outages.
- Failing to filter video storyboards once caused weekly quota to plummet by 40%+; high-frequency idle polling is strictly prohibited; optimize trigger timings.
Plans effective October 12, 2026:
| Plan | Price | Quota | Includes Bot |
|---|---|---|---|
| Plus | $8/mo | - | No |
| Premium | $30/mo or $300/yr | 4x | Yes |
| Super | $100/mo or $1000/yr | 15x | Yes |
| Ultra | $200/mo or $2000/yr | 50x | Yes |
Acceptance & Verification
Permissions and Directories
- Go to Account Settings > "General → Agent → Execute on this computer"; the status must be "Never allow". Bots are strictly prohibited from automated posting and payments, and fabricating data is forbidden.
- Check the 7 subdirectories under
/workspace/content-team/, and fill in account positioning, sample posts, and forbidden terms in00-profile/voice.md.
Research, Writing & Dry Run
- Fetch 3 leads, spot-checking that 2 links are accessible and backed by original text; mark missing data as "No public data found"; speculating figures or follower counts is forbidden.
- After confirming the Brief, generate the initial draft: the first two sentences present core facts directly, paragraphs stay within 2 to 4 sentences, the end includes factual basis and pending confirmation items, and forbidden terms are completely avoided.
- Reviewed drafts only verify without introducing new arguments; they must never be published automatically without human instructions. Run
restore.shonce in the test environment to verify that dependent environments are properly set up.
Further Reading
Official Documentation
- Plans & Billing
- Bot Teams and Collaboration
- Cloud Computer Environment and Configuration
- Group Chat Collaboration
- Routines and Automation
Community Practical Sources
- Building a We-Media Team with Grok Bot: A Step-by-Step Tutorial | Adrian Punk
- How to Use Grok Bot Effectively for We-Media | Kin
- Turn Your Tweets into a Personal Persona Website: A Step-by-Step Tutorial from Feature Analysis to Online Sharing Using Grok Bot
- Zero-to-One Guide to Building a Fully Automated Agent Team: Complete End-to-End Workflow from Grok Bot Setup to Multi-AI Collaboration (10,000-Word In-Depth Guide)
- 铁柱's Tweet Collection ③: Practical Strategies and Case Studies